What to watch: the health checklist
A running cluster reports its own state. Most of what the cluster reports needs no action from you: MooseFS restores redundancy, levels stored space across Chunkservers, and cleans up after deleted files by itself. This page sorts the readings by how fast a bad value causes damage. Each entry says what a bad value means and where the value is shown. Each entry also says what the cluster does about it on its own, because knowing when not to react matters as much as knowing when to react.
The health readings come from the Leader
In MooseFS PRO PRO (PRO Edition only), the chunk matrix, both self-check loops, and the missing files report exist only on the Leader, because a Follower runs neither loop. The GUI and mfscli omit those sections entirely while the cluster has no Leader. A missing section therefore means that the cluster is between Leaders, not that its counts are zero. Community Edition runs one Master Server. Every reading on this page comes from that server.
Check these the moment something looks wrong
These answer one question: whether all of the data is reachable right now.
missingchunks: part of the data cannot be read. The cluster does not repair it, because a missing chunk has no source left anywhere. The count is in the summary line of the chunk matrix table on the Info tab of the GUI and inmfscli -SIC, next toendangered,undergoal,stable,overgoal, andpending deletion. The cluster raises it at error severity. Recovery is described in cluster health problems.endangeredchunks: those chunks have no redundancy left, so the next failure that affects them is data loss. Same table, same summary line, also raised at error severity. The cluster is already replicating them ahead of every other repair. In the usual case, stop other maintenance and let the count fall. Self-healing explains what the state means.- The missing files report: the Missing Files table on the Info tab and
mfscli -SMFname the affected paths. However, the file loop rebuilds the table, so the table is as old as the last full pass of that loop. The table is also a per-chunk list, so one file appears once for every chunk it is missing. Use the report to find out which files are affected. Use the chunk matrix for the current count. Pass timings are in the chunk loop and the file loop. - Disconnected Chunkservers: copies held by a disconnected server stop counting toward redundancy. For this reason, the
endangeredandundergoalcounts rise within minutes of a disconnection.mfscli -SCSlists disconnected servers under "Disconnected chunkservers". The Chunkservers tab marks them, and the exporter exposesmfs_chunkservers_connected. In MooseFS PRO PRO (PRO Edition only), enough disconnected Chunkservers also cause the Leader to lose its majority. Leader election and quorum explains how many is enough. - Master Server state: the Metadata Servers table (
mfscli -SIM, and the Info tab in the GUI) gives the state of each Master Server. No Leader at all means that an election is under way. Investigate an election that has not finished within a minute. More than one Leader, Elect, or Usurper at once is raised at error severity. One arrangement is a deliberate exception. A single Leader beside a single Usurper and no Elect is the ordinary handover of the role (leader election), and the cluster raises no alert for it. The wording of both alerts is in Alerts.
One caution covers this whole group. While Chunkservers are connecting or disconnecting, the matrix counts are not trustworthy. The cluster says so: the matrix includes a line saying that counters may not be valid. Each interface words that line in its own way. A warning-level alert stays active until the check completes. Both self-check loops are held back for the same reason. A jump in missing right after an election or a restart is a reading in progress. Trust the count taken after that alert clears.
overgoal and pending deletion are not faults. They count work that the cluster has queued for itself: surplus copies to remove and chunks of deleted files to reclaim. Both counts fall as the chunk loop reaches the chunks concerned (deletion).
Put these under a standing alert
These change slowly enough that watching a screen is the wrong tool. Rules and thresholds are in alerting. The messages the cluster produces on its own are in Alerts.
- Free space, per disk and per server: writes stop before the disks are actually full. Nothing inside the cluster frees space for you. Read it per disk on the Disks tab or in
mfscli -SHD, per server inmfscli -SCS, and for the whole cluster inmfscli -SIG. The cluster warns at 90% used and raises an error at 99% used, for a single disk and for a whole Chunkserver alike. The cluster takes a nearly full Chunkserver out of the pool for new chunks instead of filling it to the end. To get the space back, follow space management. - Disk errors: MooseFS assesses a disk from failed reads and writes alone, never from SMART data. For this reason, keep the operating system's own disk monitoring alongside MooseFS. A disk that fails enough operations inside the tolerance window is marked
damagedand dropped from service in one step. The cluster replicates what the disk held. A disk's status and the time of its last error are on the Disks tab and inmfscli -SHD. The counting rule is in disk error handling and disk removal. undergoalchunks: below the redundancy their Storage Class requires, still fully readable, and already being repaired. A count that rises while a job runs and falls when the job ends is expected behavior, not a fault. A count that stays the same is the signal. Such a count means that the cluster cannot repair the chunks, not that the cluster is not trying. Self-healing names the conditions that block the repair.- Maintenance mode: the cluster holds repairs back while a disconnected Chunkserver is in maintenance mode. The failure here is therefore a Chunkserver left in that mode after the work on it has finished. The Maintenance column shows the mode on the Chunkservers tab of the GUI and in the Chunkserver list of the CLI. Each interface spells it in its own way. The exporter exposes the same value as a label on
mfs_chunkservers_misc. Maintenance mode covers what the mode suspends and when each variant expires by itself. - Metadata health: the Metadata Servers table also shows how far each Follower PRO (PRO Edition only) is behind the Leader, when the last metadata image was written, how long that write took, and how it ended. The cluster alerts on the delay, on a write that runs long, and on two Master Servers that saved the same version with different checksums. A Follower that is no longer synchronized resynchronizes from the Leader without help. The readings are explained in metadata ID, version, delay, and checksum and save states.
- License headroom PRO (PRO Edition only): a size-limited license counts raw stored data. The cluster stops accepting new data once the limit is reached. An expired time-limited license shuts the cluster down. Both are announced in advance at warning severity. The size limit escalates to error severity while headroom still remains. The time limit reaches error severity only after the license has expired. The current figures are in
mfscli -SLI. - Location state PRO (PRO Edition only): a location switched to I/O-only or offline is a maintenance state. The cluster raises a warning for as long as the state lasts. In I/O-only mode the cluster stops replication, rebalancing, and deletions for that location. In offline mode clients cannot connect to that location at all. Read the state in
mfscli -SLOor on the Locations subtab of the Info tab, because the Prometheus exporter does not expose it. - Error-level lines in the system log:
erroris the level that a module writes when the module cannot continue past what happened. The module usually stops right after that. Those lines appear in the system log of the machine concerned. Examples are a Master Server that could not write its metadata where it belongs, or a disk that read back a block that does not match its checksum. A job stalled on a disk and a Metalogger that is no longer connected are logged at warning level or below. A feed limited toerrorlines therefore does not include them. A module that has stopped reports nothing at all afterwards, so its last lines show why it stopped. Forward what MooseFS writes aterrorfrom every machine that runs a module. The lines to recognize on sight, and the settings that decide how much each module writes, are in logs.
Review these on a schedule
- Where the space is going: a fill rate is only visible over weeks. An alert fires only when a disk is already near the top of its range. Cluster totals are in
mfscli -SIG. The history of those totals is in charts and statistics. - How the work is spread across Chunkservers: a server that is consistently busier than its peers appears as an overloaded queue state on the Chunkservers tab and in
mfscli -SCS. The cluster raises a warning for it. The cluster levels stored space across servers on its own (rebalancing). Leveling stored space is not the same as leveling client traffic, so you have to explain an uneven load yourself. - Disk operation times:
mfscli -SHDreports per-disk read, write, and fsync times. The exporter exposes them too. MooseFS publishes no threshold for these times, so they are useful only for comparison. Keep a baseline for your hardware and watch for a disk whose times move away from those of its peers. - How old the last metadata image is:
mfscli -SIMgives the time, the duration, and the outcome of the last save. The Master Server writes an image on the schedule set byMETADATA_SAVE_FREQinmfsmaster.cfg, once an hour by default. The Master Server raises a warning when a single write runs long. - Master Server memory:
mfscli -SMUreports what the Master Server is using. There is no threshold to alert on, because the right figure depends on the number of files and chunks you keep. Compare what the Master Server is using against the calculation in Master Server RAM and against your own growth. - Inactive mounts: a client that lost its connection without disconnecting cleanly stays on the Mounts tab and in
mfscli -SMDas inactive. Such a client does not endanger the cluster. The cluster reports the client as information, but that client cannot use the cluster until the client reconnects. A mount that keeps reappearing there points at the network between the client and the cluster. - How fast the loops are turning: both self-check loops report the start and end times of their last finished pass. Comparing a pass against earlier passes tells you whether housekeeping is keeping up with the cluster it has to walk. There is no expected duration to compare against, so the baseline is your own. Cluster health parameters explains how to read the report. The chunk loop and the file loop covers the mechanism behind it.
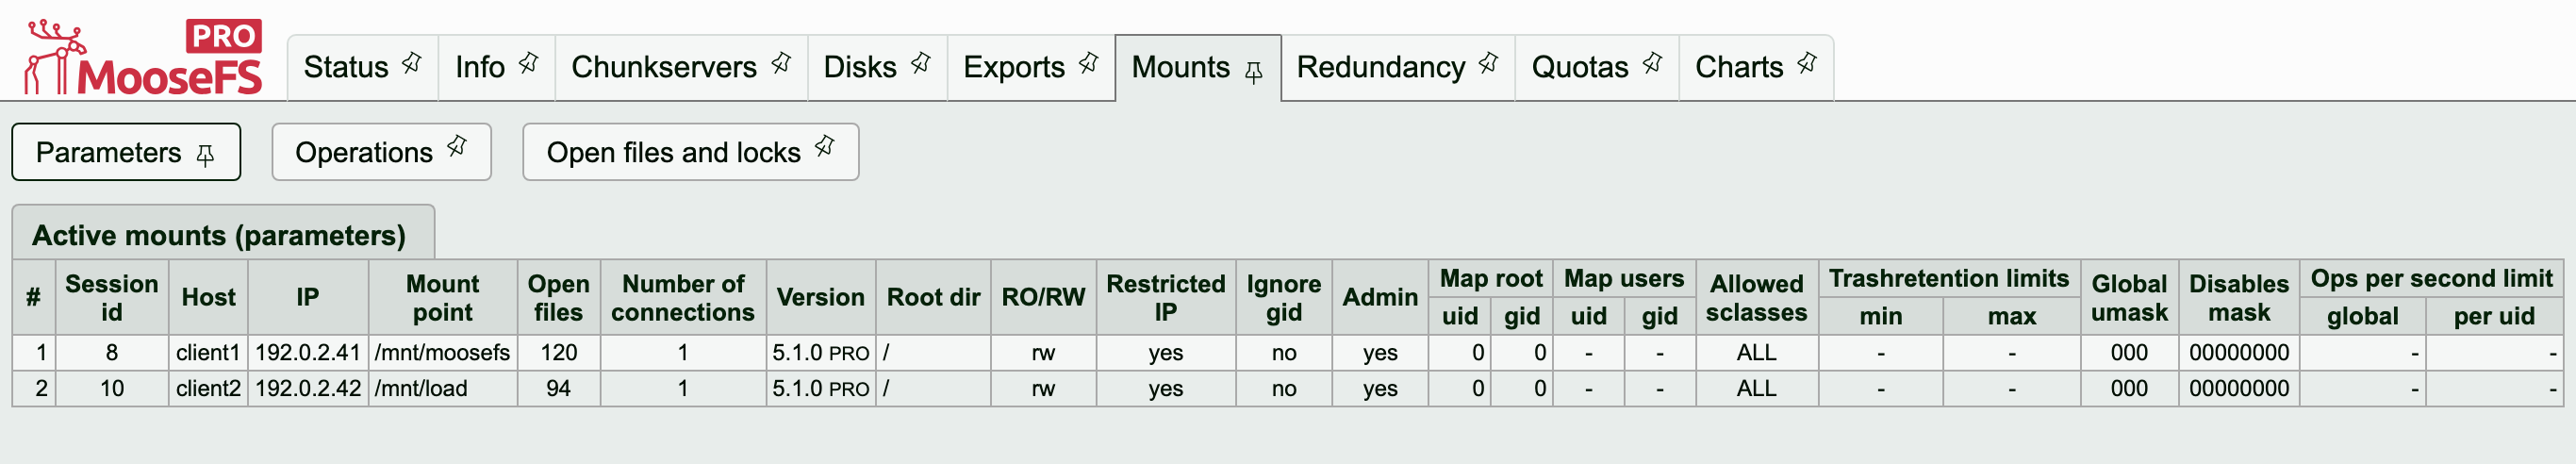
The Parameters subtab under Mounts, where a session that lost its client stays listed until the session expires or is ended by hand.
Some things are watched from outside the cluster
MooseFS reports on the cluster, not on the machines under it. These readings have to come from ordinary host monitoring. A gap here costs as much as a gap in the cluster's own alerts.
- Free space where the Master Server writes: the metadata image and the changelogs go to
DATA_PATHinmfsmaster.cfg. A Master Server that cannot write there falls back to emergency locations and then stops. No MooseFS reading shows that free space, so watch the file system from the host. The failure and its repair are in Master Server problems. - Processes and ports: a component that is down reports nothing, so its readings disappear rather than turning into zeros. Check the processes and the listening ports with whatever already watches your other servers. Network ports says which port belongs to which component.
- Network latency and packet loss: each mount times its own exchanges with the Master Server and reports the figure in its
.statsfile. The mount logs a line of its own when the round trip exceeds 100 ms. MooseFS measures neither the path between a client and a Chunkserver nor packet loss anywhere. A fault on those paths therefore appears in the cluster as a timeout, not as a reading. Measure the network itself from the hosts, and read the symptoms in network problems.
Reading stops here, but deciding starts in Troubleshooting
Cluster health parameters explains in detail what each counter in the matrix and in the loop reports. The places these values are read from have pages of their own: the GUI, the CLI, Prometheus metrics, charts and statistics, logs, and alerting. None of these readings answers a question about one file, one client, or one moment that has already passed. For such a question, use diagnostic tools instead. When one of these readings turns bad, go to start from the symptom.